
Discrete Diffusion Sudoku and Diffusion Lore

Updated: May 18, 2025

A short attempt at a small portion of the diffusion Family Tree
Discrete diffusion is the lesser known (but growing in popularity) sibling to the familiar Gaussian diffusion models. Despite their differences, these two both fall under the family of models defined by:
A random iterative destruction forward process. When reversed, it allows for generation.
A model that either directly or indirectly learns the score of the distribution, the "direction" to move in to increase the probability of a sample and move to a less noisy state.
Continuous diffusion typically looks like this:

Discrete Diffusion you can think of looking something like this (masked diffusion case, and typically this is with latent tokens passed to a decoder instead of being done in pixel space)

Discrete diffusion seems to be the accepted name now for a large family of methods that involve probabilistic removal/replacement of local patches of a piece of data and using a model that predicts a categorical distribution to recover the original clean sample.
Gaussian diffusion involves globally interpolating a piece of data with Gaussian noise, such that the result is a mixture of noise and signal. At higher noise levels, noise dominates while signal is sparse, and vice versa for the lower noise cases. When we normalize both data and noise to std=1, we can measure how noisy the data becomes by its signal-to-noise ratio. We have a continuous state describing the mixture between signal and noise.
On the other hand, instead of a continuous signal, like pixels, discrete diffusion instead works with a categorical vocabulary. Let's say, we have a vocabulary of 8192 unique tokens. We encode our data and assign patches of it to one of these tokens, by an approach like VQGAN.

Now it doesn't make sense to add continuous noise to integer values that simply indicate the index of a vocabulary: nearby entries in the vocabulary aren't necessarily related.
So now, we have two options for noising. From a single token, we can either assign it to a special value that never occurs in the data, like [MASK] (absorbing end-state diffusion), or we can randomly switch it to another entry of the vocabulary (stochastic end-state diffusion?).

What's interesting here is that noise is no longer a continuous spectrum but rather a binary variable: the token is either its original state or the noised state (MASK/random value) it got swapped with.
This introduces a challenge in adapting from continuous diffusion. We want to have many different noise levels to perturb and predict from. Instead, we can think of our noise level as representing a probability that an individual token gets swapped with its noise copy. So at noise level 0.5, we'd expect half the tokens to be swapped.
Notice now that the noise level is no longer consistent everywhere. With our Gaussian diffusion, the same amount of noise is applied everywhere around the data (granted, we may sample values closer to 0, so this in a way constitutes less noise). Here, however, a portion of the image may remain entirely intact while other tokens have been swapped.
An ongoing challenge of discrete diffusion is actually identifying what kind of SNR we are at. Let's imagine, for instance, in the top right corner of every image is a special token that indicates not information about the specific patch of the image but instead classifies the image globally, like "cat, dog, horse, car..." etc. Noising this token may have a different effect from removing other tokens, so it's hard to say what canonical noise level we are actually at. Another example of this is with diffusion language models. Removing tokens like "the" or "a" does not constitute a huge loss of information: they are easily predictable from the grammar of the sentence, and the message of the text is well preserved without them. Other words of a sentence may be much more important, and their loss would confer a more substantial loss of information. This is also a reason the MASK option is preferable to the random replacement case. If we happen to replace a word with a synonym, this may not confer too much loss of information, but a more out-of-place word could result in more significant destruction.
Once upon a time I thought I had come up with discrete diffusion when I was seeking a way we could reduce the neural network modeling load by augmenting it with wave function collapse. In particular, I was interested in ways of building 3D models from learned super-voxel tokens and having some kind of ruleset for how they should be built.
I called the approach Wave Function Collapse BERT for Images.
Wave function collapse is used for procedural generation, often for something like randomly generated dungeons in games. There is a "hard" rule set that says as one goes about placing different kinds of tiles, only certain tiles are allowed to neighbor them, thus reducing the uncertainty of what remains.
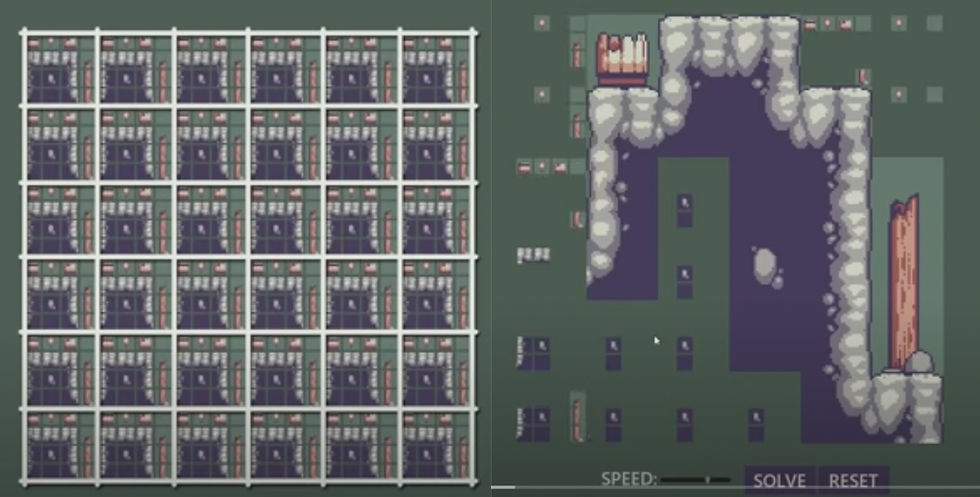
For instance, the image on the left shows our fresh grid. Every tile currently can assume any state because there are currently no constraints. However, once we place down, say, a tile with a barrel on it, we know that just below it needs to be a rock. On the right, we can see that the options for what we can choose have been reduced.
I was quite fascinated by the results of autoregressive image generation at the time, but it takes a criminally long time to place all of the tokens of an image (which may easily be in the 1000s) one by one. It was also strange to me the ordering we placed tokens in. Why do we start at the top left corner and place tokens in raster order? This could allow us to sample multiple tokens simultaneously, especially as the context becomes more clear, more and more tokens become "free", similar to how we have fewer options to choose from as more of the dungeon tiles are filled out.
Pretend in these diagrams instead of sampling from words, we are sampling visual tokens.


Discrete Diffusion is kind of like wave function collapse where the rules are "soft" (meaning that which tokens are allowed to coexist with each other is based on probabilities of what occurs rather than absolute rules) and are learned by the model. Because of mechanisms like attention as well, we can have learned rules that have global awareness of the board as well.
Sudoku is an example of a problem that can be solved via wave function collapse, which made it seem like a fun thing to try with discrete diffusion. I observed that this was able to learn to predict valid sudoku boards starting from scratch with as few as 2000 training steps.


sc88 dạo này thấy nhắc hoài nên mình cũng tò mò bấm vào xem thử cho biết thôi, kiểu xem giao diện họ làm ra sao chứ không có ý chơi bời gì. Vào cái là thấy trang nhìn khá thoáng, không bị nhét chữ dày đặc nên lướt một vòng cũng nhẹ mắt. Mình để ý họ chia nội dung thành từng khối rõ ràng, nhìn qua là biết phần nào với phần nào, kéo xuống không bị lạc. Cái mình thích nữa là thanh menu đặt ngay chỗ dễ thấy, bấm đổi mục qua lại khá nhanh, không phải mò mẫm. Nói chung cảm giác thân thiện với người mới, kiểu mở lên là hiểu ngay đang ở…
Bài viết dễ hiểu và thực tế, cảm ơn bạn đã chia sẻ. Đoạn nói về lạm phát với lãi kép đúng cái mình đang thắc mắc bấy lâu. Mình cũng hay theo dõi thống kê XSMB mỗi ngày nên gom lại thành một trang tổng hợp để tiện tra cứu nhanh. Ai quan tâm số liệu cập nhật theo ngày thì ghé thử https://divisionmidway.org/jobs/author/soicauxsmbpro/
Trước đây mình hay loay hoay cả buổi chỉ để chọn addon cho Minecraft PE, rồi thử ghép với resource pack xem có bị xung đột hay làm máy giật không mới dám cài. Dần dần mình rút kinh nghiệm là ưu tiên shader dạng nhẹ cho máy yếu, thêm vài map mới để đổi gió cho thế giới đỡ nhàm. Trong group cũng thấy nhiều người chia sẻ mấy addon kiểu furniture hoặc alien invasion, có kèm đánh giá sao nên mình đỡ phải tải bừa rồi xoá. Mình nghĩ mấy thứ này không nên nghe truyền miệng thôi, quan trọng là nguồn có cập nhật đều. Hôm trước mình đọc vài gợi ý trên thuvienmc.com nên tìm nhanh…
Mình thường lướt tin về bitcoin rồi xem thêm vài góc nhìn phân tích kỹ thuật để nắm nhịp lên xuống của thị trường crypto mỗi ngày. Có mấy bài dự đoán giá kèm cập nhật altcoin, memecoin thì mình dễ ghép lại bức tranh chung hơn trước khi quyết định vào lệnh hay đứng ngoài quan sát. Tầm giữa ngày mình hay ghé https://tapchibitcoin.io/ để đọc nhanh, sau đó tự mở biểu đồ lên đối chiếu lại cho chắc. Thỉnh thoảng mình cũng xem chia sẻ trong cộng đồng, nhiều người nhắc nên tham khảo thêm phân tích on-chain và vài tin vắn được chọn lọc vì thường bám dữ liệu thực tế. Với các coin lớn như ETH,…
Mình chơi xổ số kiểu giải trí là chính, nên thường chỉ ngó kết quả cho vui chứ không đặt nặng chuyện đổi đời. Trước đây nghe bạn bè bàn tán đủ loại “cầu” với mẹo này kia, mình cũng thử theo dõi một thời gian cho biết. Dần dần thấy đôi lúc có vài chi tiết lặp lại khiến mình chú ý hơn, nhưng vẫn tự nhắc là đừng quá tin. Mỗi lần đọc mấy bài nhận định, mình hay ghi lại vài ý ngắn rồi chờ kết quả để đối chiếu, xem có phải mình đang tự hợp lý hóa không. Trúng chút thì vui, còn sai thì coi như trải nghiệm. Gần đây mình đọc thêm để…